S3 Faker Mock Data Generator
Cloud Tooling • Data Automation
Synthetic Cloud Data Generation Suite
Zero-Cost Cloud Emulation: Simulates full AWS S3 object storage workflows locally via containerized LocalStack, eliminating cloud testing infrastructure expenses.
Architecture & Data Pipeline
graph LR
    A["Declarative JSON Config"] --> B["Faker Generation Engine"]
    B --> C["Vectorized Pandas Processing"]
    C --> D["Multi-Format Serializer (CSV / JSON / Parquet)"]
    D --> E1["Local Storage Volume"]
    D --> E2["LocalStack S3 (Local Emulation)"]
    D --> E3["Production AWS S3 (Direct Upload)"]
Executive Overview
S3 Faker is a developer-first data synthesis tool designed to generate high-volume, realistic datasets driven by declarative JSON configuration schemas. The generated artifacts can be written to the local filesystem or streamed directly to an Amazon S3 bucket or local containerized LocalStack emulator.
The system addresses a critical bottleneck in modern data engineering: acquiring compliant, realistic test data for ETL pipeline benchmarking without incurring cloud storage costs or risking PII data leaks.
Technical Challenges & Architectural Solutions
1. Accurate Cloud Storage Emulation
- Challenge: Simulating production S3 bucket policies, multipart uploads, and credential chains locally without AWS cloud spend.
- Solution: Integrated
fsspec,s3fs, and LocalStack containerization to ensure transparent parity between local test harnesses and live production endpoints.
2. High-Throughput Memory-Efficient Synthesis
- Challenge: Generating millions of synthetic records risked Out-Of-Memory (OOM) errors during string serialization.
- Solution: Designed a streaming chunk-based generator that streams records directly through compression filters to Parquet and CSV buffers with constant memory consumption.
3. Declarative Schema-Driven Customization
- Challenge: Allowing engineers to define complex relational schemas without modifying the underlying Python engine.
- Solution: Built a dynamic JSON schema interpreter supporting custom distributions, localized locales, foreign key dependencies, and field type coercions.
CLI Workflow & Example Usage
# Generate synthetic dataset locally
python -m s3_faker --config schema.json --records 50000 --format parquet

# Stream directly to LocalStack S3 emulator
python -m s3_faker --config schema.json --target s3://test-bucket/data/ --endpoint http://localhost:4566
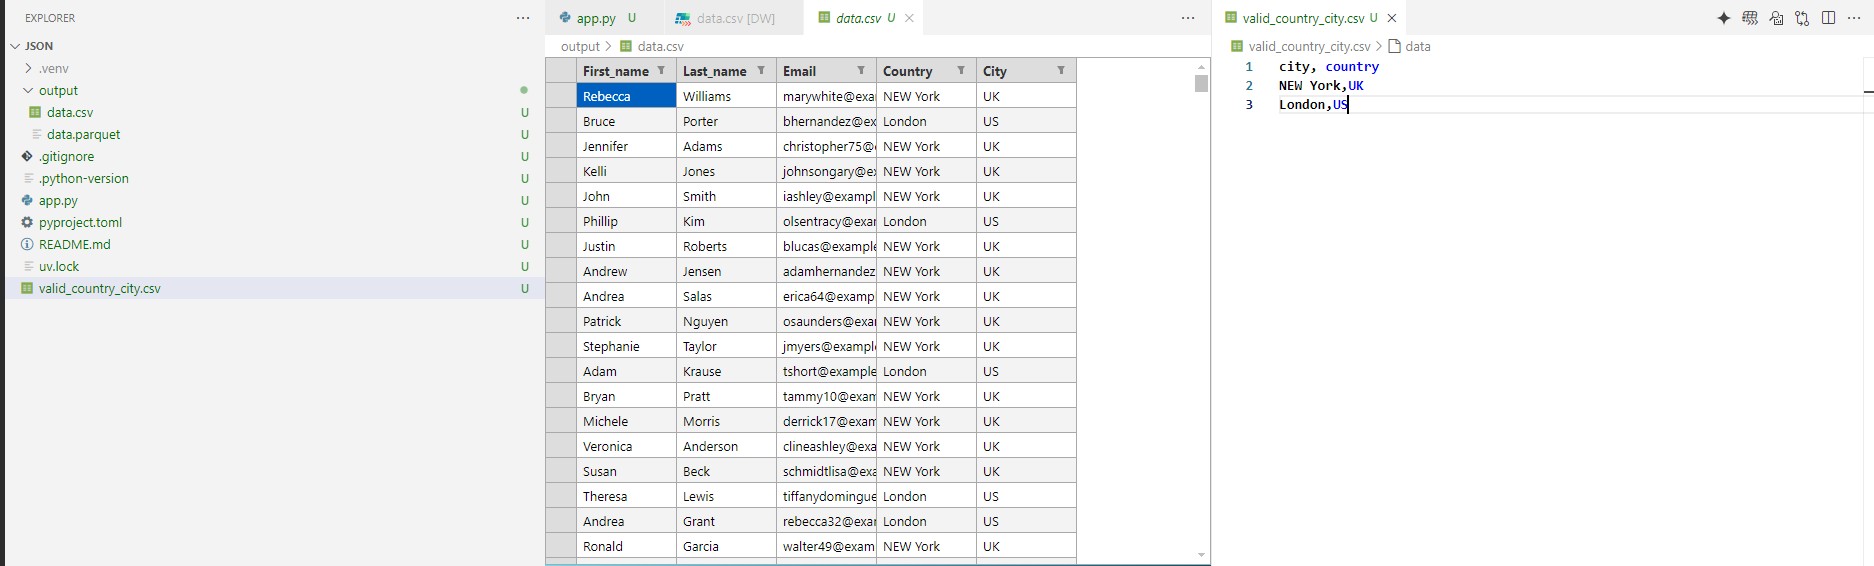
Verification & Workflow Visuals
LocalStack Emulation Environment
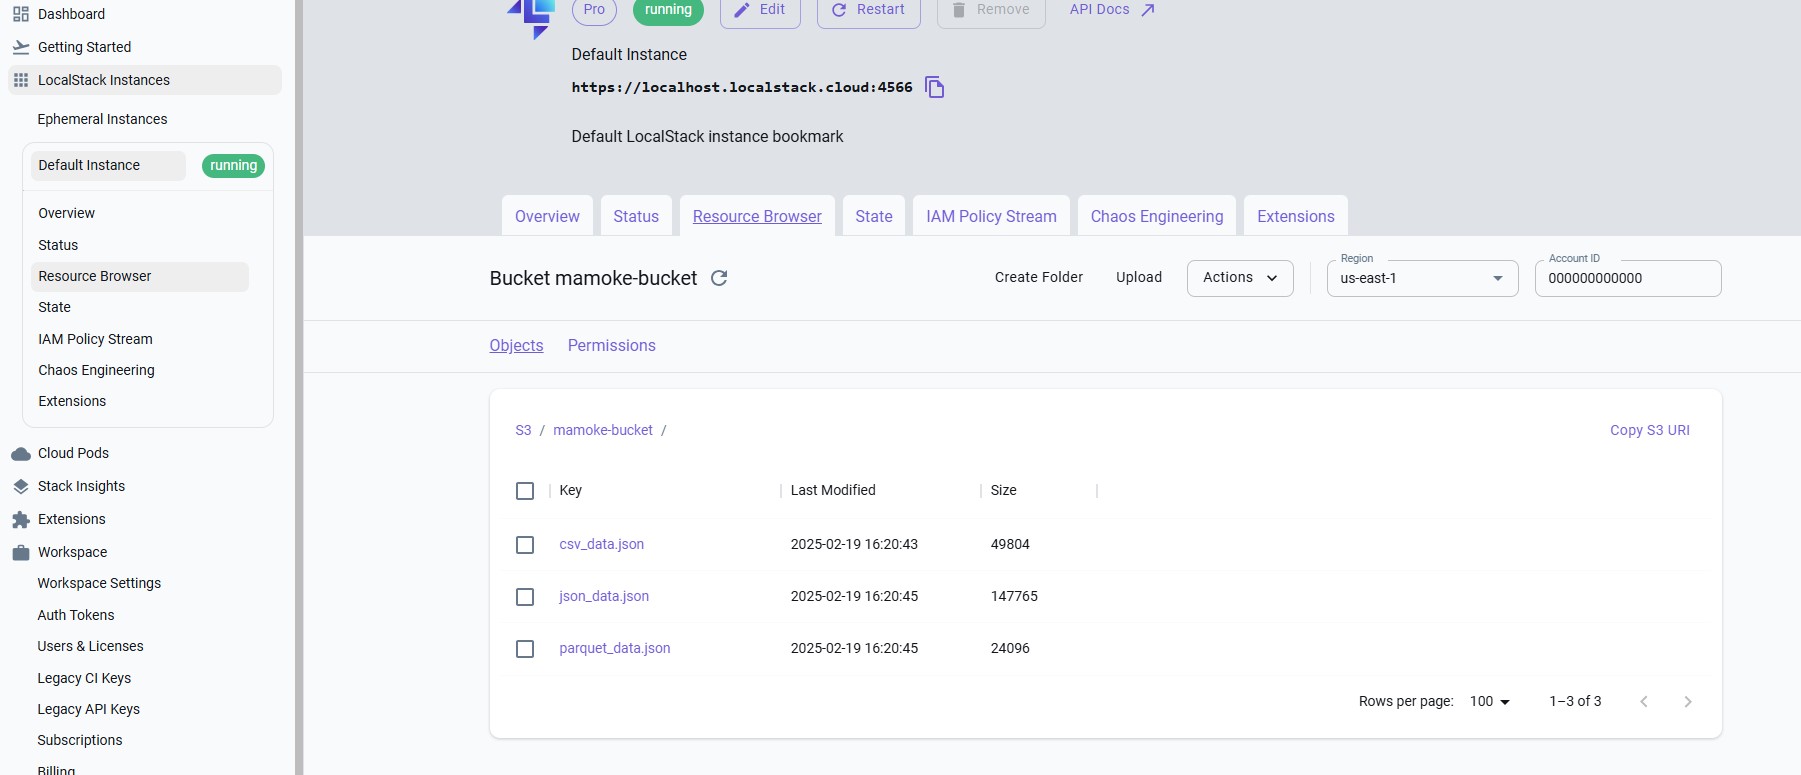
Data Synthesis & Upload Execution